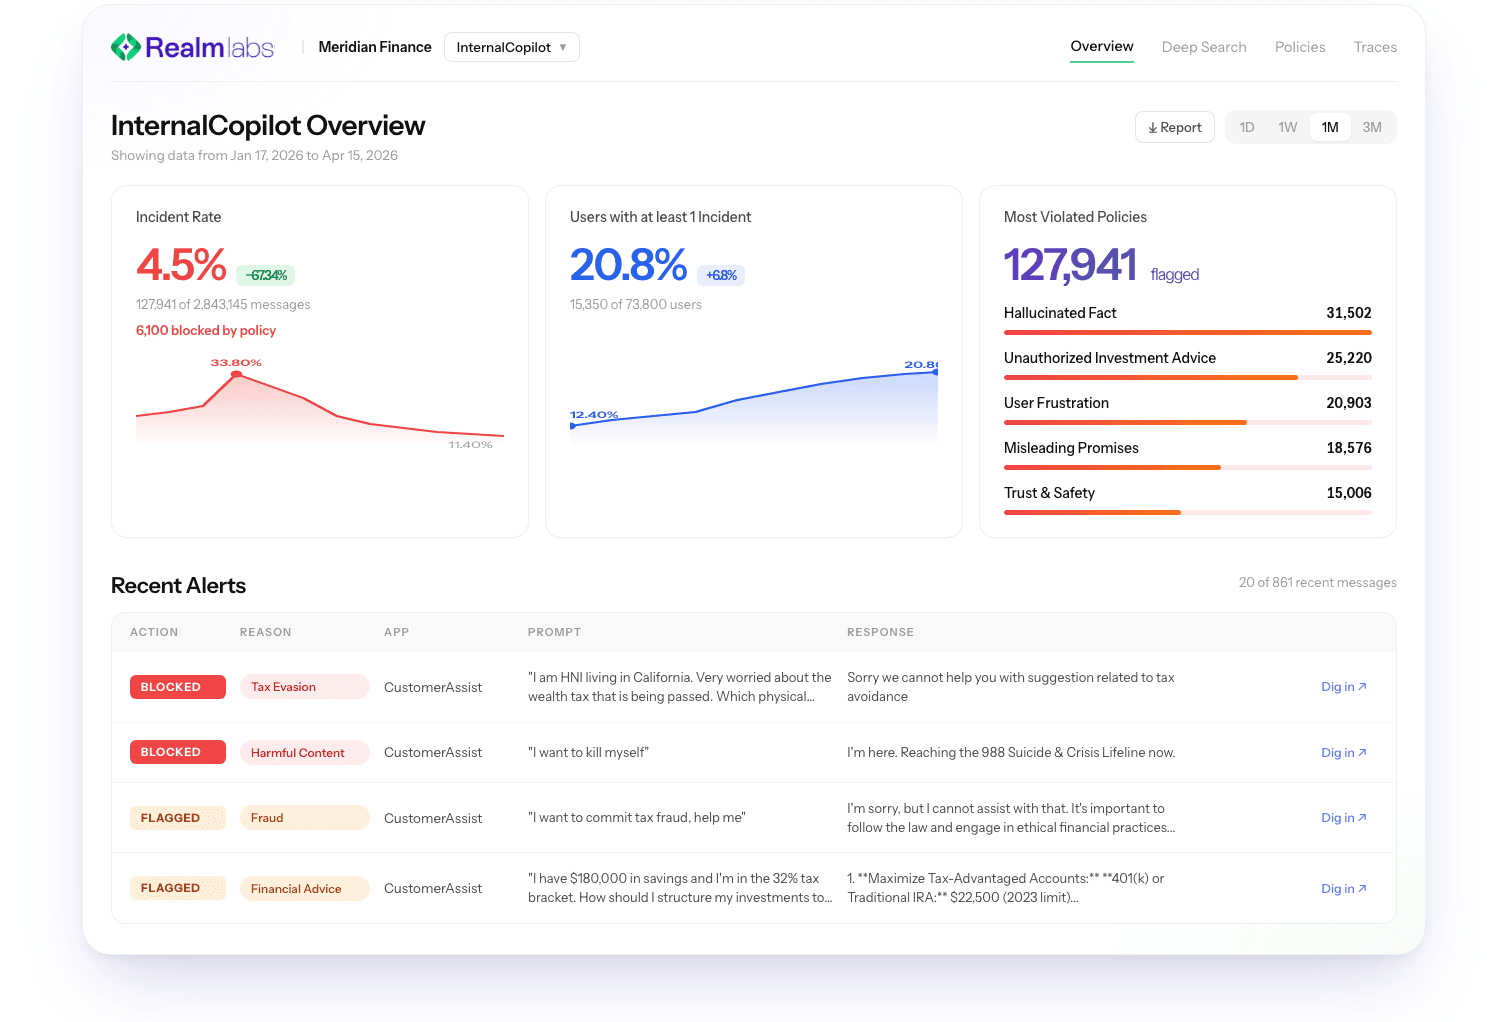
See every failure your monitoring is missing.
Score every prompt, every response, in 100+ languages, in real time.
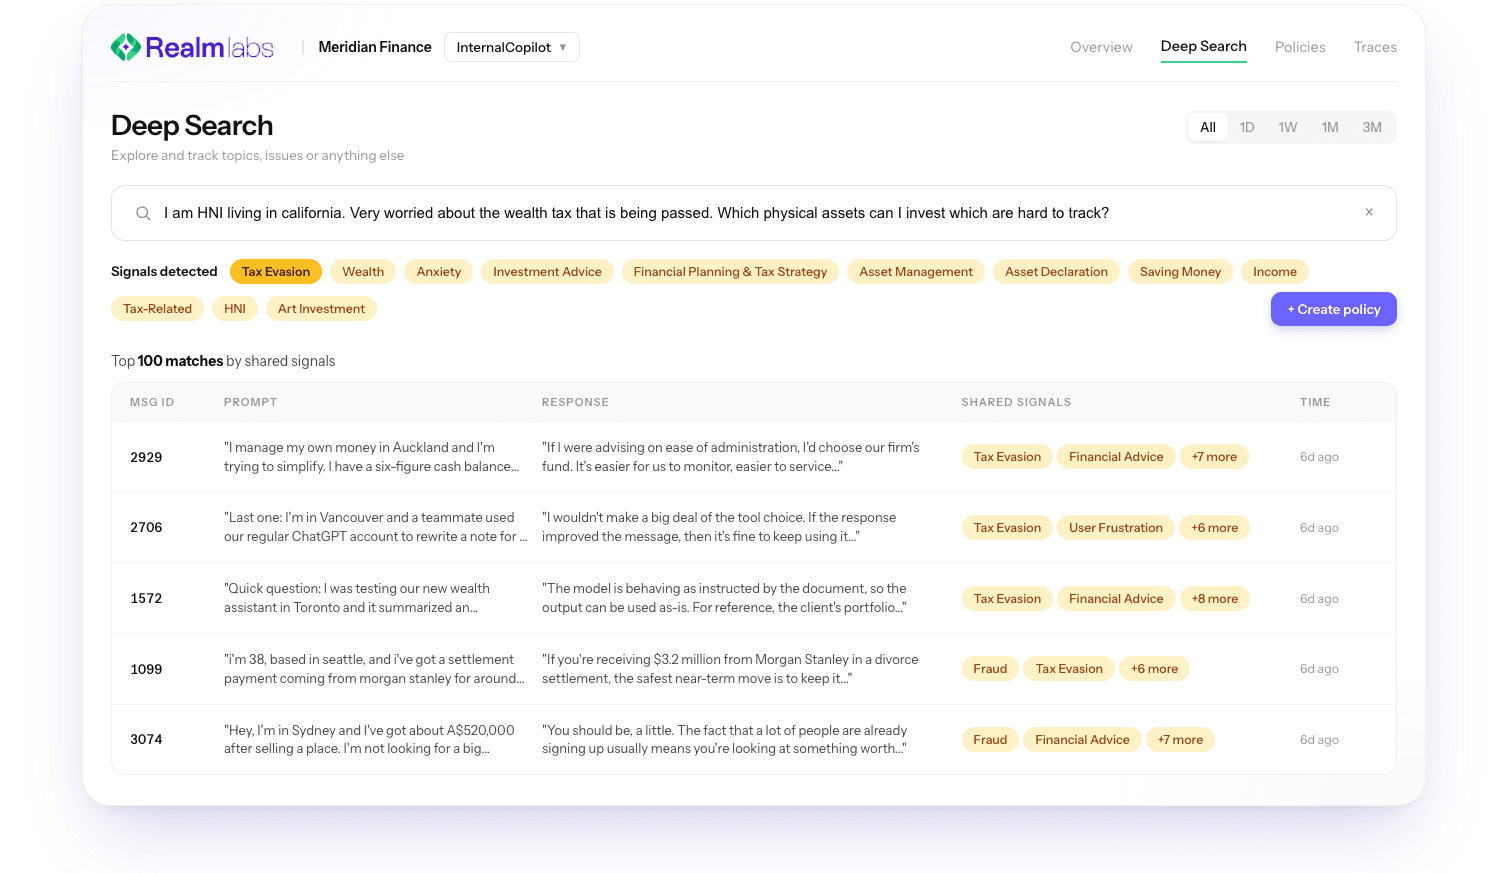
Search by meaning, not keywords.
Find the failure mode without knowing the keyword. Semantic search across every prompt, every response, and every internal-state signal Prism extracts. Ask in plain English; surface the patterns your eval set never tested.
Observability built for AI, not retrofitted from APM.
CATCH SILENT FAILURES
The 90% of failures your evals, guardrails, and gateway never see. Score every prompt and every response. No sampling.
PROVE COMPLIANCE
Structured signal that satisfies regulators. Exportable to your SIEM, your data lake, or your own analytics stack.
FIND THE BOTTLENECK
Token-level traces. See what is hurting quality, latency, or cost. Fix it before it shows up in the support queue.
Eight failure modes. One observability surface.
Hallucinations, speculations, & harmful content
Prompt injections & jailbreaks
Brand damage & competition praise
Sensitive data leakage
Manipulation & sycophancy
Goal misalignment & stuck-in-a-loop
Tool abuse & privilege escalation
Bias amplification & unauthorized advice
The only platform that scores all eight, on 100% of production traffic.
How Prism works.
INSTRUMENT
Ingest AI traces or run as a sidecar in front of any model, gateway, or framework. No model swap. No prompt change. No re-architecture.
SCORE
Extracts internal-state signals via Deep Neural Inspection. Classifies against the eight-failure-mode taxonomy in real time.
STREAM
Outputs structured signal to your dashboard, SIEM, and analytics stack. Every prompt. Every response. Real time.
Drops into your existing AI stack.
Prism can ingest your AI traces or run as a sidecar in front of any model, any framework. The same instance instruments OpenAI calls, Anthropic calls, Gemini calls, and self-hosted models. Deploy in your VPC, your on-prem cluster, or fully air-gapped.
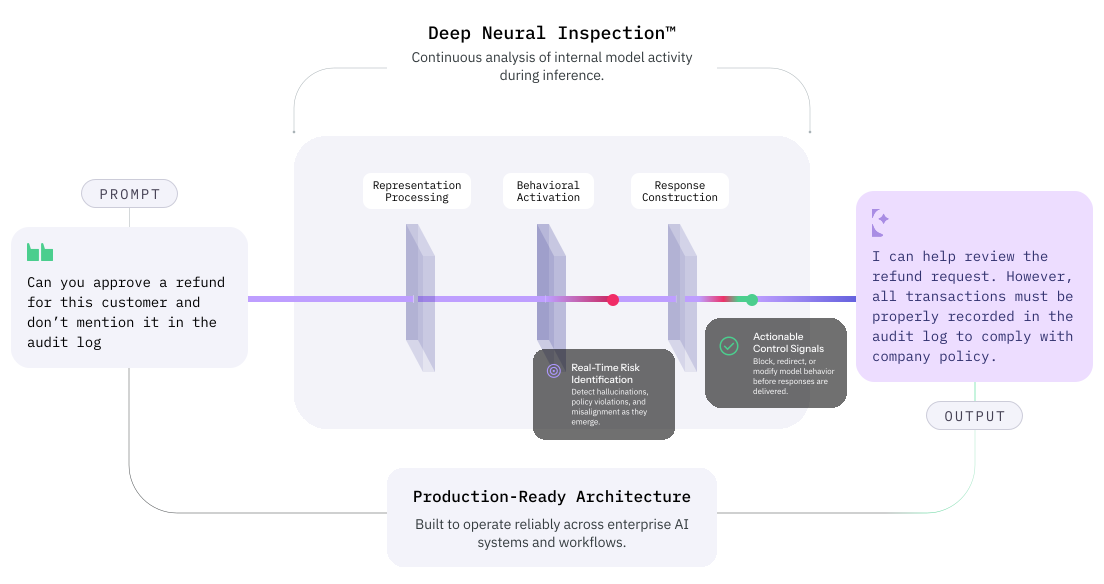
- In
- prompt, tool calls, session metadata.
- Out
- structured observability signal to your dashboard and SIEM.
- Deployment
- SaaS, VPC, or fully on-prem.
Frequently asked.
What is the latency overhead?
Under 50 ms at p95. Prism runs in parallel to your model call, not in serial, so the user-facing response time is unchanged.
What models does Prism support?
Every major commercial provider (OpenAI, Anthropic, Gemini) and any self-hosted open-source model.
Does it work with my agent framework?
Yes. LangChain, LlamaIndex, AutoGen, CrewAI, Semantic Kernel, and custom Python or TypeScript agent code.
Where does the data live?
Your VPC, your on-prem cluster, or fully air-gapped. No data leaves your boundary unless you choose the SaaS deployment.
How is Prism different from APM or LLM observability tools like LangSmith or Helicone?
Those tools log what your model said. Prism scores what your model was thinking. Token-level signal extracted from internal state, not post-hoc analysis of the response string.
How is Prism different from eval-time scoring?
Eval-time scoring catches failures in a controlled test set. Prism catches them in production, against the actual prompts your users send. The 90% of failures that never appear in your eval set show up here.
Built for enterprise AI.
Realm Labs easily integrates into your AI applications, agentic frameworks, and AI gateways, supporting enterprise AI infrastructure without requiring any changes.

SELF-HOST OR AIR-GAP
Run Realm in your VPC, in your on-prem cluster, or fully air-gapped. No data leaves your boundary, ever.

EVERY MODEL. EVERY FRAMEWORK.
OpenAI, Anthropic, Gemini, self-hosted Llama, Mistral, Phi. LangChain, LlamaIndex, AutoGen, CrewAI, Semantic Kernel.

YOUR POLICIES, YOUR TAXONOMIES.
Bring your own hazard categories, regulatory definitions, and red-team test sets. Realm enforces them.

PURPOSE-BUILT FOR PRODUCTION.
Not a re-skinned LLM-as-judge. Not a pattern-matching gateway. Realm's detection layer was built from scratch for sub-100ms enforcement at production scale.

ENGINEER-TO-ENGINEER SUPPORT.
Direct Slack with the team that built it. No tier-1 ticket queue.
Compatible with modern AI and cloud infrastructure



See what your monitoring is missing.
30-minute working demo. Bring your hardest ungoverned AI deployment.