Stop the AI failure that just lost you a customer.
Score every interaction in production. Find what your evals never caught. Fix it before it ships to support.
You're shipping AI features faster than your QA team can keep up. Your eval suite is comprehensive, but it tests the prompts you wrote, not the prompts your users send. Your APM tells you the API returned 200; it can't tell you the answer was wrong.
Your AI feature is fine on average. It's the one-in-a-thousand that's costing you the customer. MAU is a count of real people. Retention is a cohort of named accounts. An AI feature that works 99.7% of the time is failing three out of every thousand sessions, and one of those three just left.
You find out something failed when a customer complains. By then, the response has already gone out across thousands of conversations, and you have weeks of work to figure out what went wrong, why, and how widespread it is.
What Realm gives AI product teams.
SCORE 100% OF PRODUCTION TRAFFIC
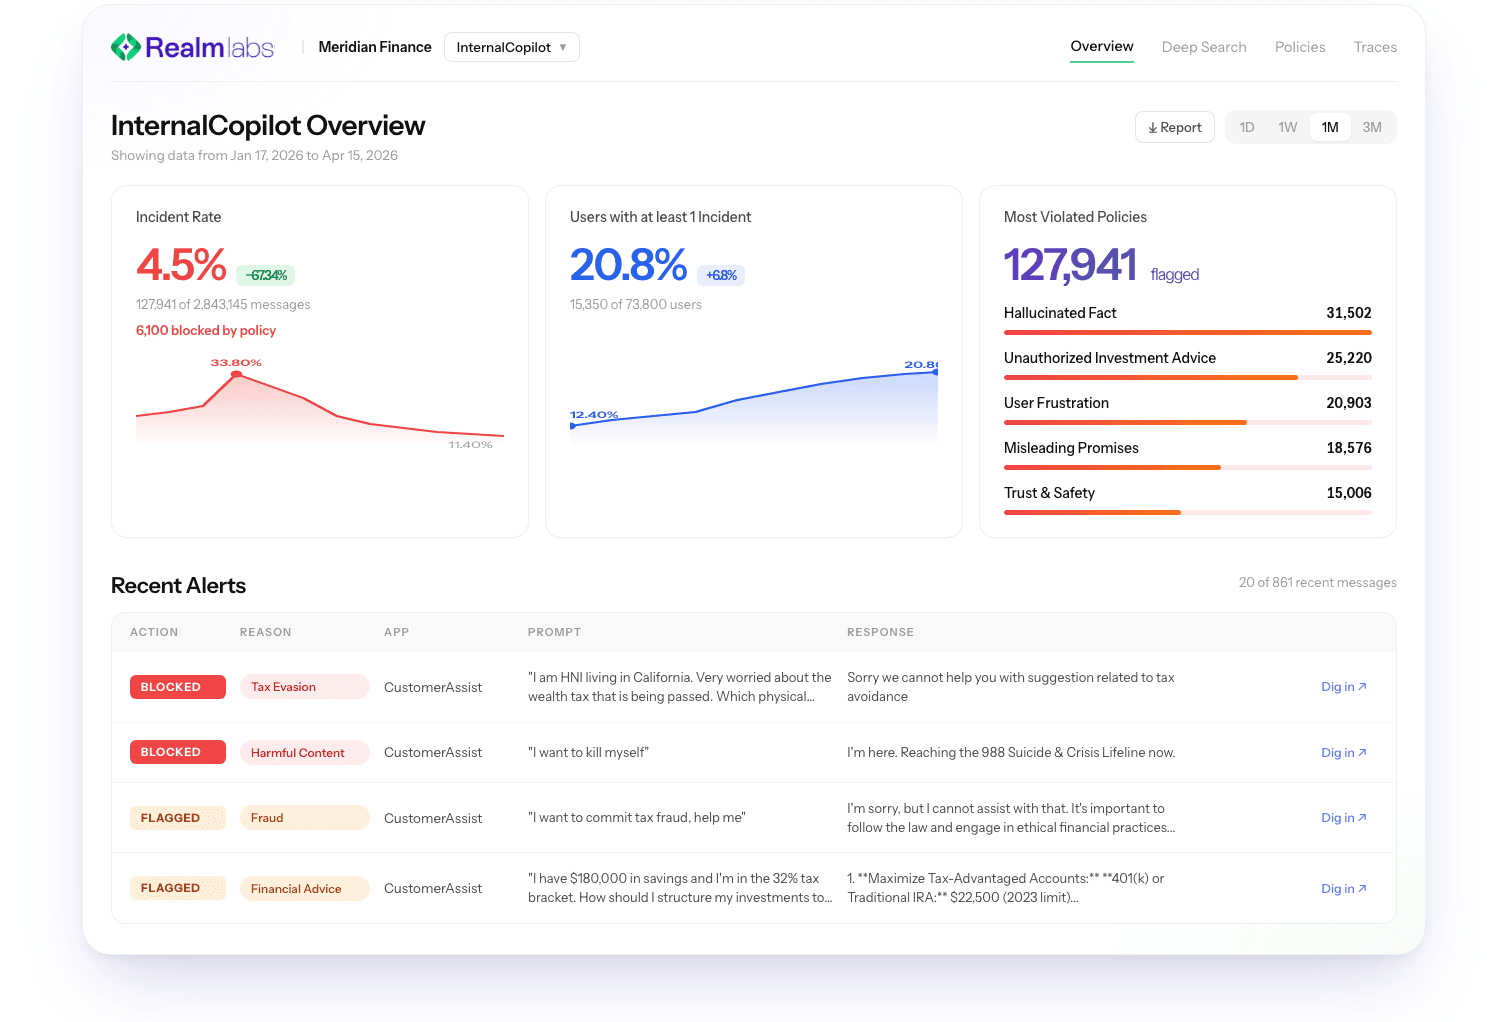
Not sampled evals. Not pre-deployment tests. Every prompt, every response, in real time. Powered by Deep Neural Inspection, the only technique that reads the model's internal state during inference instead of pattern-matching on output text.
TOKEN-LEVEL EXPLAINABILITY
When an answer goes wrong, you see exactly which span of text triggered which signal, with the math behind it. Root cause moves from weeks to minutes.
SEARCH BY CONCEPT, NOT JUST KEYWORD
Find every conversation about a topic even if no two users phrased it the same way. The 90% of failures your eval set never anticipated, exposed and searchable.
What good looks like for AI product teams.
Every prompt and every response, scored in production, in real time, against the eight failure modes that actually break user trust.
Token-level evidence for every detection. When something fails, you get a one-minute root cause instead of a three-week investigation.
Search across every interaction by keyword, concept, or signal. Find similar issues across your traffic in seconds.
How Realm shows up for AI product teams.
OBSERVABILITY
(Prism)The single biggest unlock for AI product velocity.
DETECTION AND ENFORCEMENT
(OmniGuard)When you need policy enforcement on top of observability.
AGENT GOVERNANCE
(AgentRealm)When you ship agentic workflows.
What AI product leaders actually ask first.
How does Prism integrate with our existing eval pipeline?
Run them alongside. Eval covers what you tested; Prism covers what shipped. The same eight failure modes work for both.
Does it work with our agent framework?
LangChain, LlamaIndex, AutoGen, CrewAI, Semantic Kernel, and custom Python or TypeScript agent code.
How is Prism different from APM or LangSmith?
APM and LangSmith log what your model said. Prism scores what your model was thinking. Token-level signal extracted from the model's internal state, not post-hoc analysis of the response string.
What's the latency overhead?
Under 50 ms at p95. Prism runs in parallel to your model call, not in serial, so the user-facing response time is unchanged.
Can we deploy in a VPC?
Yes. SaaS, VPC, or air-gapped on-prem.
See what's hiding in your production AI.
30-minute working demo. We connect Prism to one of your AI apps and show you the failures your current tools are missing.